Adithya S Kolavi
Research Engineer at Hugging Face · Scaling RL Environments in the Open
About
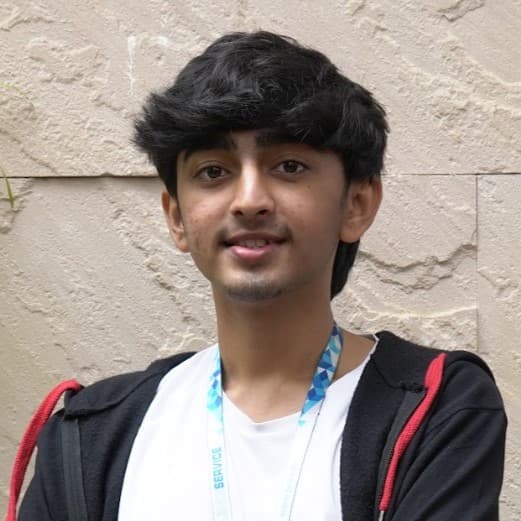
I'm a Research Engineer at Hugging Face, working on scaling reinforcement learning environments in the open: the infrastructure, environments, and training recipes that let open models learn across coding, computer use, simulation, multilingual, and scientific domains. Before this, I founded CognitiveLab, the open-source lab behind Ambari-7B and Nayana (backed by Meta's LLaMA Impact Grant), and built agentic memory and real-time agents at Microsoft Research and knowledge-graph retrieval at Apple. My work has appeared at ICCV, NAACL, AAAI, NeurIPS, and CHI venues, and my open-source projects have 15k+ GitHub stars.
Work Experience

Hugging Face
Building infrastructure to scale RL environments across data generation, training, and evaluation, including FineEnvs, an open ecosystem of cross-domain RL environments and training recipes. Built multi-harness RL training around OpenEnv (TRL, Harbor, OpenReward), created Repo2RLEnv for synthetic coding data generation, and authored the Ultimate Guide to RL Environments (25k+ reads).
Microsoft Research
Built a real-time voice agent for talking directly with video content, which was patented and won the Microsoft Global Hackathon among 10k+ participants. Developed enterprise-scale agentic memory across the Microsoft stack with 40% lower inference latency and 90%+ retrieval accuracy, resulting in a second patent and technology transfer to M365 Copilot.
Open Source
Publications
Papers at ICCV, NAACL, AAAI, NeurIPS, CVPR, and CHI venues
M3DR: Towards Universal Multilingual Multimodal Document Retrieval
TRACE: Transparent Reasoning and Attribution Chains for Extended Multimodal Contexts
A framework for transparent, attributable reasoning over long multimodal contexts, linking each reasoning step back to its supporting evidence.
News
Latest updates and highlights
FineEnvs Reaches 7 RL Environment Recipes and 500+ GitHub Stars
FineEnvs now has seven end-to-end RL environment recipes spanning coding, data science, games, simulation, and multilingual OCR and ASR, each with open environments and training code.
Launched Multilingual RL Environments for OCR and ASR
Released OpenEnv environments for document OCR, layout, and VQA across 22 languages and speech recognition across 102 FLEURS languages, turning existing SFT datasets into RL environments with ~1M OCR and ~500K ASR examples.
OpenAI Math Environments Trend on the Hub
The OpenAI Math RL environment dataset trended on Hugging Face for about a week, with 11K+ downloads, as the first step toward reproducible math RL recipes for small models.
Latest Writing & Talks
Guides, articles, and talks on RL environments and open AI
Research Projects
FineEnvs
An open ecosystem of cross-domain RL environments, post-trained models, training recipes, and reproducible artifacts spanning coding, computer use, simulation, multilingual, biology, and more.
Repo2RLEnv
Open-source library for synthetic coding data generation, unifying multiple repository-to-task approaches into one pipeline for reproducible RL environments and coding tasks at scale.
NetraEmbed
State-of-the-art multilingual multimodal document retrieval with dense (NetraEmbed) and multi-vector (ColNetraEmbed) variants, reaching 0.716 NDCG@5 (+152% over baselines) across 22 languages. Ships with the NayanaIR benchmark (28k+ document images, 5.4k+ queries).
Indic Eval/Leaderboard
Developed an evaluation framework for Indic Large Language Models, accommodating multiple translated benchmarks and a leaderboard around it for comparison.
Ambari-7b
India's first Kannada bilingual LLM utilizing the LLama2/3 base model, fine-tuned across multiple stages with 1 billion Kannada tokens and tokenization efficiency by 85%
YoloGemma
Testing and evaluating the capabilities of Vision-Language models (PaliGemma) in performing computer vision tasks such as object detection and segmentation.
VARAG
Vision-Augmented Retrieval and Generation : a system integrating textual and visual information, enhancing RAG by 35% and improving contextual precision by 60%.
Mixture of Lora Experts
A novel architecture facilitating the dynamic serving of multiple finetuned LLMs by swapping Lora Adapters during inference.
ViViD
A state-of-the-art Vision-Language model specialized in converting complex PDFs into markdown with high speed and efficiency.